Note: the links and images in this document may point to external sources. Please review them before opening.
Nginx 502 Bad Gateway fix: 5 Critical Steps to Stop Production Crashes
Written by Thomas C (20+ Years Enterprise Linux Engineering)
⚠️ Is your production web application returning 502 errors right now?
If your website is down, customers are complaining, and restarting PHP-FPM only restores traffic for five minutes before it crashes again, our senior engineer can triage and stabilize your upstream pool immediately under our 1-hour emergency response protocol.
Request 1-Hour Emergency Incident Triage ($199) →
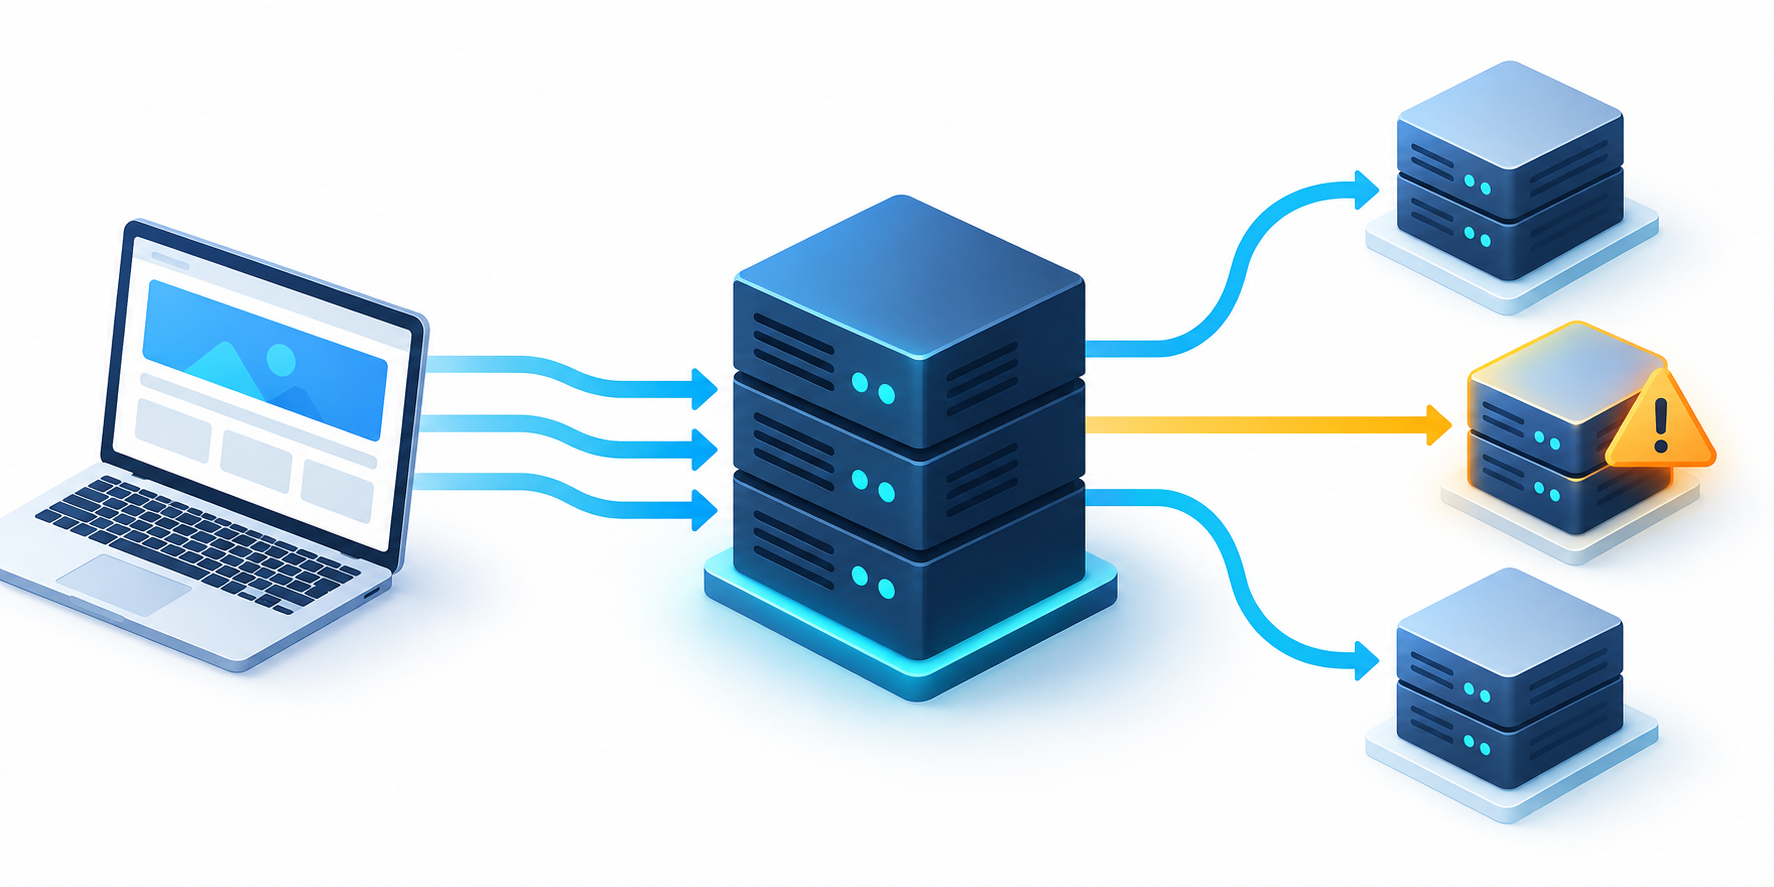
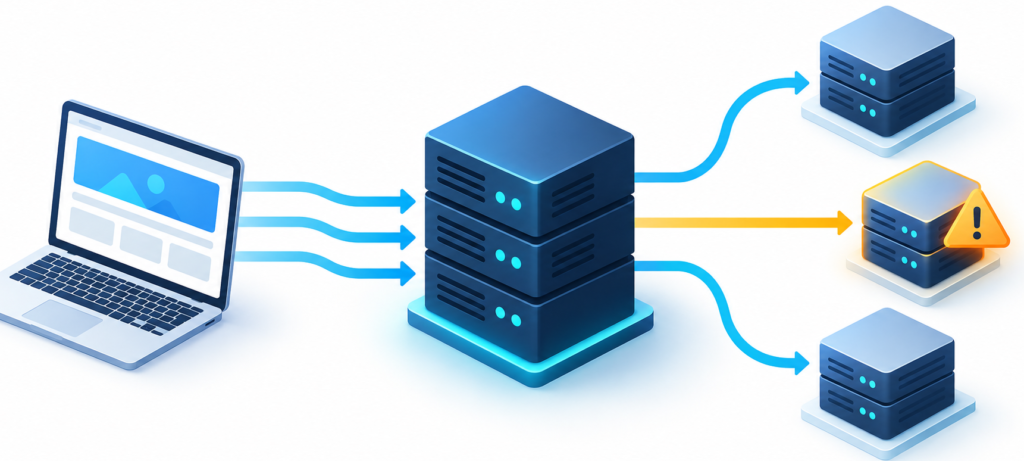
Few alerts cause panic quite like a sudden wave of 502 Bad Gateway errors across your production web fleet. Whether you run a high-traffic WooCommerce store, a SaaS API cluster, or an agency hosting 40 client sites on a single cloud VPS, a 502 status code means one thing: Nginx is running properly as a reverse proxy, but the upstream application service (usually PHP-FPM) has crashed, timed out, or refused to answer.
Blindly restarting Nginx or rebooting the server does not solve the root cause. Within minutes, traffic resumes, the connection backlog fills, and the gateway crashes again.
This emergency operational guide provides the exact diagnostic steps, memory calculation formulas, and configuration adjustments needed for a permanent Nginx 502 bad gateway fix across production Ubuntu, Debian, RHEL, and Rocky Linux environments.
Step 1: Diagnose the Exact Error Signature for an Nginx 502 Bad Gateway Fix
Refreshing your browser or looking at HTTP status codes teaches you nothing about the underlying failure. To apply an accurate nginx 502 bad gateway fix, you must inspect the raw upstream communication logs in real time.
Open a root terminal session and monitor the Nginx error log:
tail -n 50 -f /var/log/nginx/error.log
Every 502 error originates from one of three distinct failure signatures. Identify which one matches your log output before making configuration changes:
 to unix:/run/php/php8.2-fpm.sock</text><text x=”25″ y=”95″ fill=”%23EF4444″ font-family=”monospace” font-size=”13″>failed (111: Connection refused) while connecting to upstream</text><text x=”25″ y=”130″ fill=”%23F8FAFC” font-family=”monospace” font-size=”13″>2026/03/30 14:10:15 [error] 14210#14210: *8502 upstream timed out (110: Connection timed out)</text><text x=”25″ y=”155″ fill=”%23F59E0B” font-family=”monospace” font-size=”13″>while reading response header from upstream, client: 198.51.100.24</text><text x=”25″ y=”195″ fill=”%2314B8A6″ font-family=”monospace” font-size=”13″>[DIAGNOSIS] Upstream pool queue saturated. Immediate socket triage required.</text></svg>)
Signature A: Connection refused (111)
connect() to unix:/run/php/php8.2-fpm.sock failed (111: Connection refused) while connecting to upstream
- Root Cause: The PHP-FPM daemon has crashed, halted, or exceeded its listen queue backlog entirely.
Signature B: No such file or directory (2)
connect() to unix:/run/php/php8.2-fpm.sock failed (2: No such file or directory) while connecting to upstream
- Root Cause: Nginx is looking for a Unix domain socket path that does not exist on the filesystem (common after automated PHP version upgrades).
Signature C: Connection timed out (110)
upstream timed out (110: Connection timed out) while reading response header from upstream
- Root Cause: PHP-FPM accepted the request, but all worker processes are blocked on slow database queries, external API deadlocks, or long-running scripts exceeding
request_terminate_timeout.
Step 2: Fix Crashed Daemons and Socket Permissions (Signatures A & B)
If your error log shows Connection refused or No such file or directory, your first step in an nginx 502 bad gateway fix is verifying the systemd service state.
1. Check PHP-FPM Service Status
Run the status command across all installed PHP versions:
systemctl status "php*-fpm"
If the service is marked as failed or inactive (dead), check the systemd journal for exit codes:
journalctl -u "php*-fpm" -n 30 --no-pager
2. Verify Socket File Creation and Ownership
When PHP-FPM boots, it creates a socket file defined in its pool configuration. If Nginx runs as www-data or nginx, but the socket belongs to root, Nginx cannot communicate with the upstream backend.
Inspect socket ownership:
ls -la /run/php/
Verify that ownership matches your Nginx process user:
srw-rw---- 1 www-data www-data 0 Mar 30 12:00 php8.2-fpm.sock
If permissions are wrong, edit your pool configuration (typically /etc/php/8.2/fpm/pool.d/www.conf or /etc/php-fpm.d/www.conf):
; /etc/php/8.2/fpm/pool.d/www.conf
listen = /run/php/php8.2-fpm.sock
listen.owner = www-data
listen.group = www-data
listen.mode = 0660
Restart PHP-FPM and test Nginx syntax before reloading:
systemctl restart php8.2-fpm
nginx -t && systemctl reload nginx
Step 3: Resolve pm.max_children Pool Exhaustion (Signature A Under Load)
The single most common operational trigger for intermittent 502 errors is worker pool exhaustion.
Check your PHP-FPM log (/var/log/php8.2-fpm.log or /var/log/php-fpm/error.log):
grep -i "max_children" /var/log/php*-fpm.log
If you see this critical line:
[WARNING] [pool www] server reached pm.max_children setting (5), consider raising it
Every available PHP-FPM worker child is busy processing requests. Subsequent incoming connections are forced into a backlog queue. Once that queue overflows, PHP-FPM drops connections, triggering an immediate 502 Bad Gateway.
The Dangerous Mistake: Blindly Setting pm.max_children = 200
Junior developers often respond by setting pm.max_children = 200. On a server with 4GB or 8GB of RAM, this causes catastrophic Out-of-Memory (OOM) kernel panics. If 100 PHP workers spawn and each uses 75MB of RAM, your server consumes 7.5GB of memory instantly, freezing the kernel and killing MySQL.
The Production Calculation Formula
To implement a safe nginx 502 bad gateway fix, calculate your maximum worker ceiling mathematically based on real memory measurements:
$$
\text{pm.max_children} = \frac{\text{Total Dedicated PHP RAM}}{\text{Average Memory Per PHP Process}}
$$
Where:
$$
\text{Total Dedicated PHP RAM} = \text{Total Server RAM} – \text{OS Overhead (1GB)} – \text{Database RAM} – \text{Nginx/Redis Buffer (512MB)}
$$
How to Measure Average Worker Size in Real-Time
Run this awk pipeline on your production server during normal traffic to get the exact average process footprint in megabytes:
ps -ylC php-fpm8.2 --sort:rss | awk '{sum+=$8; count++} END {print "Average Process Memory: " sum/count/1024 " MB"}'
- Example Scenario:
- Total Server RAM: 8,192 MB (8GB)
- OS Reserve + Nginx + Redis: 1,500 MB
- Local MySQL Database: 2,500 MB
- Remaining RAM for PHP: $8,192 – 1,500 – 2,500 = \mathbf{4,192\text{ MB}}$
- Average PHP Process: 65 MB
- Safe Maximum Children: $\frac{4,192}{65} \approx \mathbf{64\text{ workers}}$
Edit your pool file (/etc/php/8.2/fpm/pool.d/www.conf):
pm = dynamic
pm.max_children = 64
pm.start_servers = 16
pm.min_spare_servers = 8
pm.max_spare_servers = 24
pm.max_requests = 1000
Senior Sysadmin Tip: Always configure
pm.max_requests = 1000. By default, PHP-FPM workers can run indefinitely. Because PHP code frequently has minor memory leaks in third-party libraries, recycling each worker after 1,000 requests prevents gradual memory creep from consuming all swap space.
Step 4: Fix FastCGI Upstream Timeouts & Buffer Stalls (Signature C)
If your error log reports upstream timed out (110: Connection timed out), your workers are not dead; they are stalled waiting on slow operations (e.g., generating 10,000-row PDF reports, processing CSV imports, or executing unindexed database queries).
By default, Nginx cuts the connection after 60 seconds, generating a 502 or 504 error.
1. Tune FastCGI Timeouts in Nginx
If your application legitimately requires extended runtime for specific backend operations, adjust timeouts inside your location ~ \.php$ block:
location ~ \.php$ {
    include snippets/fastcgi-php.conf;
    fastcgi_pass unix:/run/php/php8.2-fpm.sock;

    # Upstream Timeout Thresholds
    fastcgi_connect_timeout 60s;
    fastcgi_send_timeout 180s;
    fastcgi_read_timeout 180s;

    # FastCGI Buffer Tuning (Prevents disk-spooling of large headers)
    fastcgi_buffer_size 32k;
    fastcgi_buffers 16 16k;
    fastcgi_busy_buffers_size 64k;
    fastcgi_temp_file_write_size 64k;
}
2. Match PHP Execution Limits
Nginx timeouts must align with PHP’s own execution constraints in /etc/php/8.2/fpm/php.ini and your pool configuration:
; In php.ini
max_execution_time = 180

; In pool.d/www.conf
request_terminate_timeout = 180s
Reload both services cleanly:
systemctl reload php8.2-fpm
nginx -t && systemctl reload nginx
Step 5: Systemd Self-Healing and Real-Time Pool Monitoring
A professional nginx 502 bad gateway fix includes automated failure recovery so that an unexpected segfault does not keep production offline overnight.
1. Enable Systemd Automatic Process Respawn
Prevent PHP-FPM from remaining dead after unexpected kernel panics by adding an override configuration:
mkdir -p /etc/systemd/system/php8.2-fpm.service.d/
cat << 'EOF' > /etc/systemd/system/php8.2-fpm.service.d/override.conf
[Service]
Restart=on-failure
RestartSec=3s
EOF

systemctl daemon-reload
If PHP-FPM encounters an unhandled fatal error, systemd automatically relaunches the master daemon within three seconds.
2. Enable the PHP-FPM Status Dashboard
To monitor whether your pool is nearing capacity before an outage occurs, enable the built-in status page in /etc/php/8.2/fpm/pool.d/www.conf:
pm.status_path = /status
In your default Nginx server configuration, restrict access to localhost:
location = /status {
    fastcgi_pass unix:/run/php/php8.2-fpm.sock;
    include fastcgi_params;
    fastcgi_param SCRIPT_FILENAME $fastcgi_script_name;
    allow 127.0.0.1;
    deny all;
}
Check pool metrics from your CLI anytime:
curl -s http://127.0.0.1/status
Output:
pool:                 www
process manager:      dynamic
start time:           30/Mar/2026:10:14:02
accepted conn:        48201
listen queue:         0
max listen queue:     2
idle processes:       18
active processes:     6
total processes:      24
max active processes: 54
max children reached: 0
If listen queue climbs above 0 or max children reached is greater than 0, your pool is under-provisioned for current traffic spikes.
Technical Summary Checklist for an Nginx 502 Bad Gateway Fix
Use this quick-reference table during routine maintenance or emergency incident reviews:
| Diagnostic Target | Command / Configuration Path | Ideal Production State |
|---|---|---|
| Error Signatures | tail -f /var/log/nginx/error.log | Zero Connection refused or Connection timed out entries |
| Worker Sizing | /etc/php/8.2/fpm/pool.d/www.conf | pm.max_children derived from available RAM formula |
| Worker Recycling | pm.max_requests = 1000 | Recycles worker after 1k requests to prevent memory leaks |
| Buffer Sizing | fastcgi_buffer_size 32k; | Avoids writing large response headers to temporary disk |
| Process Recovery | /etc/systemd/system/php*-fpm.service.d/ | Restart=on-failure configured with RestartSec=3s |
| Status Telemetry | curl -s http://127.0.0.1/status | max children reached: 0 and listen queue: 0 |
When to Bring in a Dedicated Linux Operations Partner
Resolving an isolated 502 error takes 30 minutes of log analysis and pool tuning. But if your team manages multiple customer servers, e-commerce stores, or SaaS production clusters, dealing with repeated upstream crashes, memory leaks, and unmonitored backlogs consumes valuable engineering hours that should be spent writing software.
Two Ways OS Assistance Solves This Problem:
1. Immediate Crisis Rescue: 1-Hour Emergency Incident Triage ($199)
If your production server is down right now, your website is throwing 502 errors, and your in-house team is stuck, submit an emergency ticket. Our senior engineer responds within 1 hour, diagnoses the exact bottleneck, and stabilizes your stack.
👉 Request Urgent Emergency Support ($199)
2. Ongoing Fleet Health: Steady-State Linux Care ($4,000/month flat)
Never worry about unmonitored backlogs, failed SSL renewals, disk space runouts, or upstream buffer errors again. Get an embedded 20+ year senior Linux systems administrator covering your entire server estate. Unlimited servers, Monday–Friday (8h/day), one active workstream at a time.
👉 Explore Linux Care Subscription ($4,000/mo)